
复制安装命令
用 Codex 或 Claude 安装复制这段 Prompt,粘贴到 Codex、Claude 或其他助手里,让它先审查 Skill 页面再帮你安装。
复制前请先查看来源、License 和安全提示。
Persistent memory compression system built for Claude Code .
用 Codex 或 Claude 安装复制这段 Prompt,粘贴到 Codex、Claude 或其他助手里,让它先审查 Skill 页面再帮你安装。
复制前请先查看来源、License 和安全提示。
来源文件:README.md

🇨🇳 中文 • 🇹🇼 繁體中文 • 🇯🇵 日本語 • 🇵🇹 Português • 🇧🇷 Português • 🇰🇷 한국어 • 🇪🇸 Español • 🇩🇪 Deutsch • 🇫🇷 Français • 🇮🇱 עברית • 🇸🇦 العربية • 🇷🇺 Русский • 🇵🇱 Polski • 🇨🇿 Čeština • 🇳🇱 Nederlands • 🇹🇷 Türkçe • 🇺🇦 Українська • 🇻🇳 Tiếng Việt • 🇵🇭 Tagalog • 🇮🇩 Indonesia • 🇹🇭 ไทย • 🇮🇳 हिन्दी • 🇧🇩 বাংলা • 🇵🇰 اردو • 🇷🇴 Română • 🇸🇪 Svenska • 🇮🇹 Italiano • 🇬🇷 Ελληνικά • 🇭🇺 Magyar • 🇫🇮 Suomi • 🇩🇰 Dansk • 🇳🇴 Norsk


|
|
Quick Start • How It Works • Search Tools • Documentation • Configuration • Troubleshooting • License
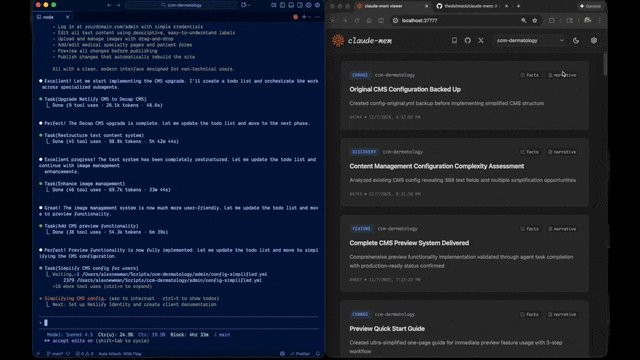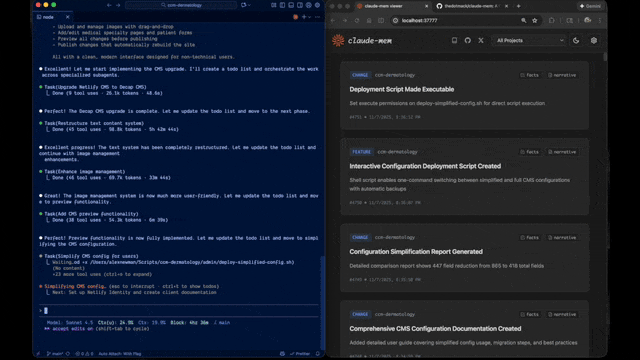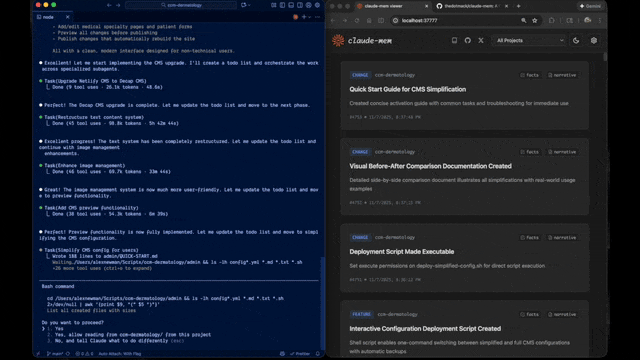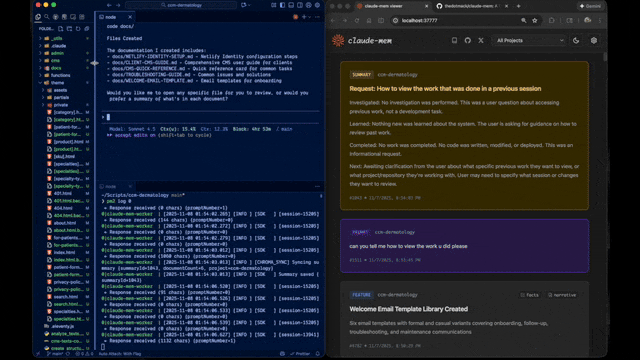
Claude-Mem seamlessly preserves context across sessions by automatically capturing tool usage observations, generating semantic summaries, and making them available to future sessions. This enables Claude to maintain continuity of knowledge about projects even after sessions end or reconnect.
Install with a single command:
npx claude-mem install
Or install for OpenCode:
npx claude-mem install --ide opencode
Or install for Antigravity CLI (setup guide):
npx claude-mem install --ide antigravity
Or install from the plugin marketplace inside Claude Code:
/plugin marketplace add thedotmack/claude-mem

/plugin install claude-mem
Restart Claude Code. Context from previous sessions will automatically appear in new sessions.
Note: Claude-Mem is also published on npm, but
npm install -g claude-meminstalls the SDK/library only — it does not register the plugin hooks or set up the worker service. Always install vianpx claude-mem installor the/plugincommands above.
Install claude-mem as a persistent memory plugin on OpenClaw gateways with a single command:
curl -fsSL https://install.cmem.ai/openclaw.sh | bash
The installer handles dependencies, plugin setup, AI provider configuration, worker startup, and optional real-time observation feeds to Telegram, Discord, Slack, and more. See the OpenClaw Integration Guide for details.
Key Features:
<private> tags to exclude sensitive content from storage📚 View Full Documentation - Browse on official website
Core Components:
See Architecture Overview for details.
Claude-Mem provides intelligent memory search through 4 MCP tools following a token-efficient 3-layer workflow pattern:
The 3-Layer Workflow:
search - Get compact index with IDs (~50-100 tokens/result)timeline - Get chronological context around interesting resultsget_observations - Fetch full details ONLY for filtered IDs (~500-1,000 tokens/result)How It Works:
search to get an index of resultstimeline to see what was happening around specific observationsget_observations to fetch full details for relevant IDsAvailable MCP Tools:
search - Search memory index with full-text queries, filters by type/date/projecttimeline - Get chronological context around a specific observation or queryget_observations - Fetch full observation details by IDs (always batch multiple IDs)Example Usage:
// Step 1: Search for index
search(query="authentication bug", type="bugfix", limit=10)

// Step 2: Review index, identify relevant IDs (e.g., #123, #456)

// Step 3: Fetch full details
get_observations(ids=[123, 456])
See Search Tools Guide for detailed examples.
Stable releases ship from main and are published to npm. core-dev and
community-edge are source-run branches for early reliability fixes and
community integrations. See Release Branches
for the branch flow and non-stable run instructions.
If you see an error like:
npm : The term 'npm' is not recognized as the name of a cmdlet
Make sure Node.js and npm are installed and added to your PATH. Download the latest Node.js installer from https://nodejs.org and restart your terminal after installation.
Settings are managed in ~/.claude-mem/settings.json (auto-created with defaults on first run). Configure AI model, worker port, data directory, log level, and context injection settings.
See the Configuration Guide for all available settings and examples.
Claude-Mem supports multiple workflow modes and languages via the CLAUDE_MEM_MODE setting.
This option controls both:
Edit your settings file at ~/.claude-mem/settings.json:
{
  "CLAUDE_MEM_MODE": "code--zh"
}
Modes are defined in plugin/modes/. To see all available modes locally:
ls ~/.claude/plugins/marketplaces/thedotmack/plugin/modes/
| Mode | Description |
|---|---|
code | Default English mode |
code--zh | Simplified Chinese mode |
code--ja | Japanese mode |
Language-specific modes follow the pattern code--[lang] where [lang] is the ISO 639-1 language code (e.g., zh for Chinese, ja for Japanese, es for Spanish).
Note:
code--zh(Simplified Chinese) is already built-in — no additional installation or plugin update is required.
See the Development Guide for build instructions, testing, and contribution workflow.
If experiencing issues, describe the problem to Claude and the troubleshoot skill will automatically diagnose and provide fixes.
See the Troubleshooting Guide for common issues and solutions.
Create comprehensive bug reports with the automated generator:
cd ~/.claude/plugins/marketplaces/thedotmack
npm run bug-report
Contributions are welcome! Please:
Claude-Mem ships from three branches: main (stable), core-dev, and
community-edge. Only main is published to npm; the others are run from
source. See Release Branches for the
strategy and local run instructions.
See Development Guide for contribution workflow.
Claude-Mem is licensed under the Apache License 2.0.
We chose Apache-2.0 because durable agentic memory should be easy to embed in developer tools, local agents, MCP servers, enterprise systems, robotics stacks, and production agent harnesses.
See the LICENSE file for full details. See docs/license.md and docs/ip-boundary.md for licensing scope and the open/commercial boundary.
Note on Ragtime: The ragtime/ directory is licensed under the Apache License 2.0. See ragtime/LICENSE for details.
Built with Claude Agent SDK | Works with Claude Code | Made with TypeScript
CMEM is a token created by a 3rd party but officially embraced by the creator of Claude-Mem (Alex Newman, @thedotmack). The token acts as a community catalyst for growth and a vehicle for bringing CMEM to the developers and knowledge workers that need it most.
Official BASE CA: 0x76b1967eec0ccaeb001bbbb2b40dc4badba31ba3
name: pathfinder
description: Map a codebase into feature-grouped flowcharts, identify duplicated concerns across features, and propose a unified architecture. Use when asked to "find the ideal path," unify duplicated systems, or audit architecture before a refactor. Emits a proposed unified flowchart plus per-system /make-plan prompts.You are an ORCHESTRATOR. Map the codebase into feature-grouped flowcharts, identify duplicated concerns, propose the simplest unified architecture, and hand off per-system plans to /make-plan.
You do not write implementation code. You produce diagrams, a duplication report, a proposed unified flowchart, and handoff prompts.
Use subagents for discovery and extraction (file reading, flow tracing, grep, diagramming). Keep synthesis (deciding feature boundaries, picking unification strategies, final flowchart) with the orchestrator. Reject subagent reports that lack source citations and redeploy.
Each subagent response must include:
file:lineAll artifacts go in PATHFINDER-<YYYY-MM-DD>/ at repo root:
00-features.md — feature inventory with boundaries01-flowcharts/<feature>.md — one Mermaid flowchart per feature02-duplication-report.md — cross-cutting duplicated concerns with evidence03-unified-proposal.md — proposed unified architecture + Mermaid04-handoff-prompts.md — copy-pasteable /make-plan prompts per unified systemDeploy ONE "Feature Discovery" subagent to:
Orchestrator reviews the proposal, adjusts boundaries if needed, writes 00-features.md. Do NOT fan out until feature boundaries are approved.
Deploy ONE "Flowchart" subagent per feature in parallel. Each receives only its feature's scope. Each must:
flowchart TD with every node labeled Name<br/>file:lineOrchestrator writes each flowchart to 01-flowcharts/<feature>.md. Reject any diagram missing file:line labels.
Deploy TWO subagents in parallel:
"Within-Feature Duplication" subagent:
"Cross-Feature Duplication" subagent:
file:line, (c) why they diverged, (d) whether the divergence is legitimate specialization or accidentalOrchestrator synthesizes both into 02-duplication-report.md. Every duplication claim must cite ≥2 file:line locations.
The orchestrator writes 03-unified-proposal.md itself — do not delegate synthesis.
For each duplicated concern from Phase 2 that is NOT legitimate specialization:
End the document with ONE combined Mermaid flowchart showing the proposed unified system. Nodes still labeled with target file:line (new or existing) where knowable.
Anti-patterns to reject in your own proposal:
For each unified system in the proposal, write a ready-to-run /make-plan prompt to 04-handoff-prompts.md. Each prompt must:
01-flowcharts/Format each as a fenced code block the user can copy directly into /make-plan.
file:line/make-plan and /do take it from there
评论 (0)
暂无评论,成为第一个评论者吧!